Problem
Small business buyers know what their team needs to do, not which model does it. A large laptop catalog turns a simple purchase into a research project.
Who it's for: an office manager or owner at a 10 to 100 person business, buying 5 to 25 laptops for their team. They aren't IT experts, they're short on time, and they want to be confident they're buying the right thing.
A good salesperson doesn't read you the whole catalog. They ask a few questions and recommend a few options. An AI concierge can do the same online, as long as every fact it states is true.
Before anything gets built, four assumptions need checking: that these buyers browse many product pages before buying or leaving, that they describe needs as tasks ("video calls, spreadsheets") rather than specs, that wrong-fit purchases drive returns, and that they want a recommendation, not just better filters. Each one has a matching check, from analytics and site search terms to five to eight short interviews with recent buyers.
Solution
A "Help me choose" concierge that asks four or five plain-language questions and returns three grounded recommendations: good, better and best, each with a reason and a tradeoff.
- Buyer clicks Help me choose
- Answers four or five plain questions
- Facts are pulled from the live catalog No invented specs or prices
- Good, better and best picks, with reasons
- Compare, add to cart, or hand off to a sales rep
The retrieval step is the safeguard. Every spec, price and stock status the buyer sees comes from the catalog, not the model.
- First version is deliberately small: business laptops only, one region, one language, small business visitors only, and checkout left exactly as it is.
- Left out on purpose: accessories and warranties until laptop accuracy is proven, consumer shoppers until one audience works, and custom pricing because it's high risk and needs sales and legal sign-off.
Research that changed the design
Before building, I shopped a large PC maker's business store the way this buyer would: 25 laptops for calls and spreadsheets, about $1,200 each. Three things I ran into reshaped the concierge.
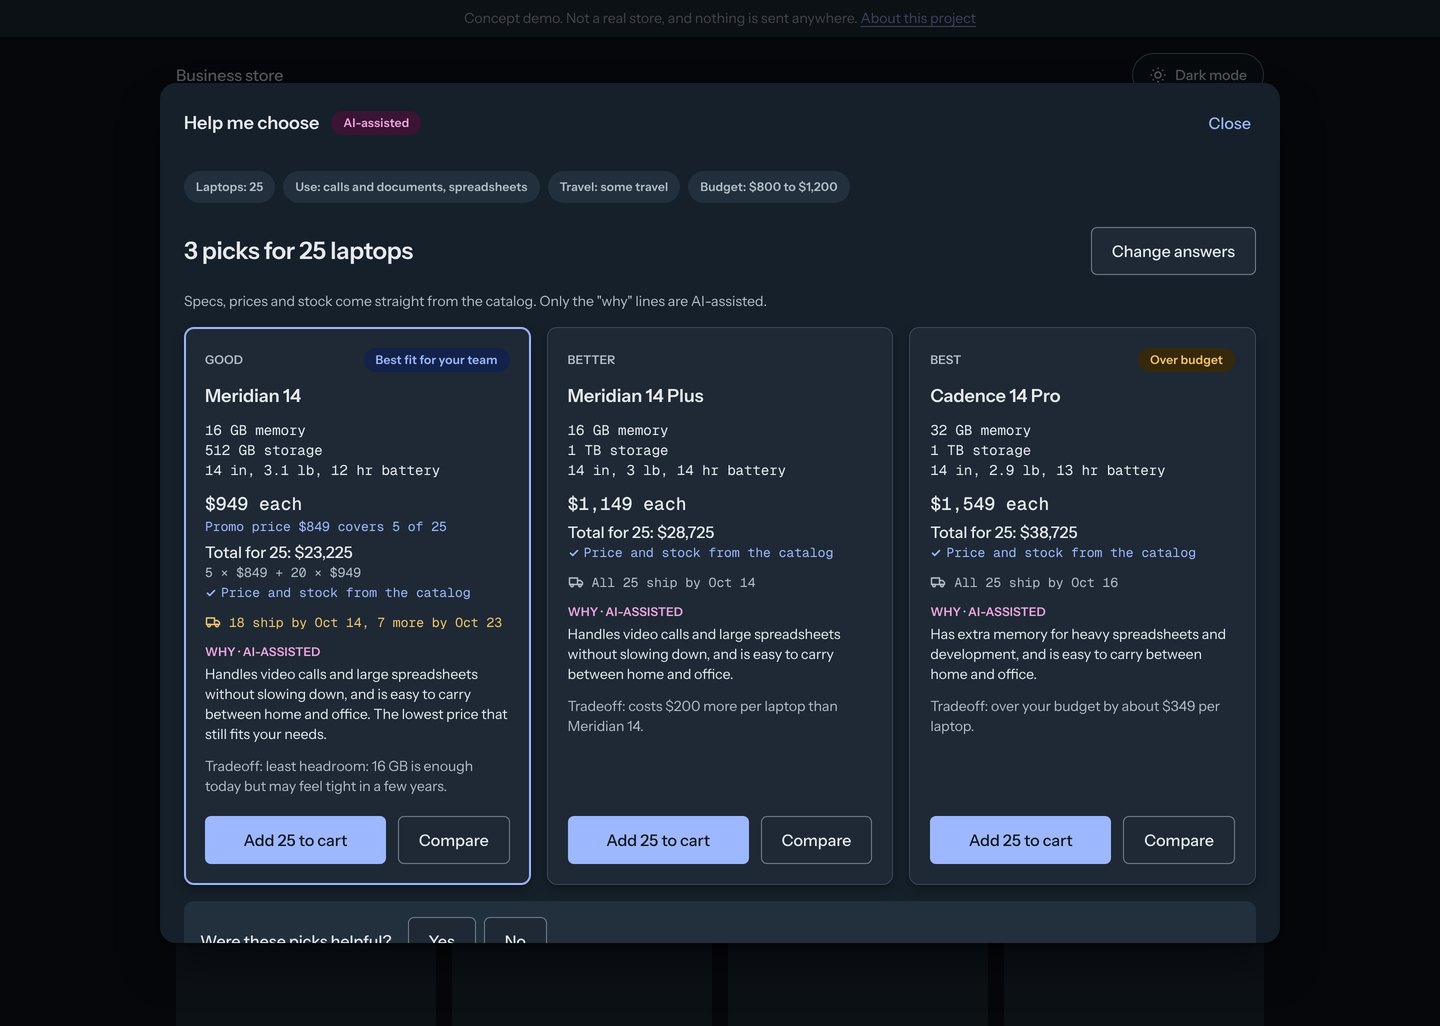
- Promo prices limited to a few units per order, mentioned only in small print. So every pick now shows the total for the whole order, and says when a promo covers only some of it.
- "In stock" that didn't mean the whole order. So stock is checked for every laptop the buyer needs, with ship dates for each batch.
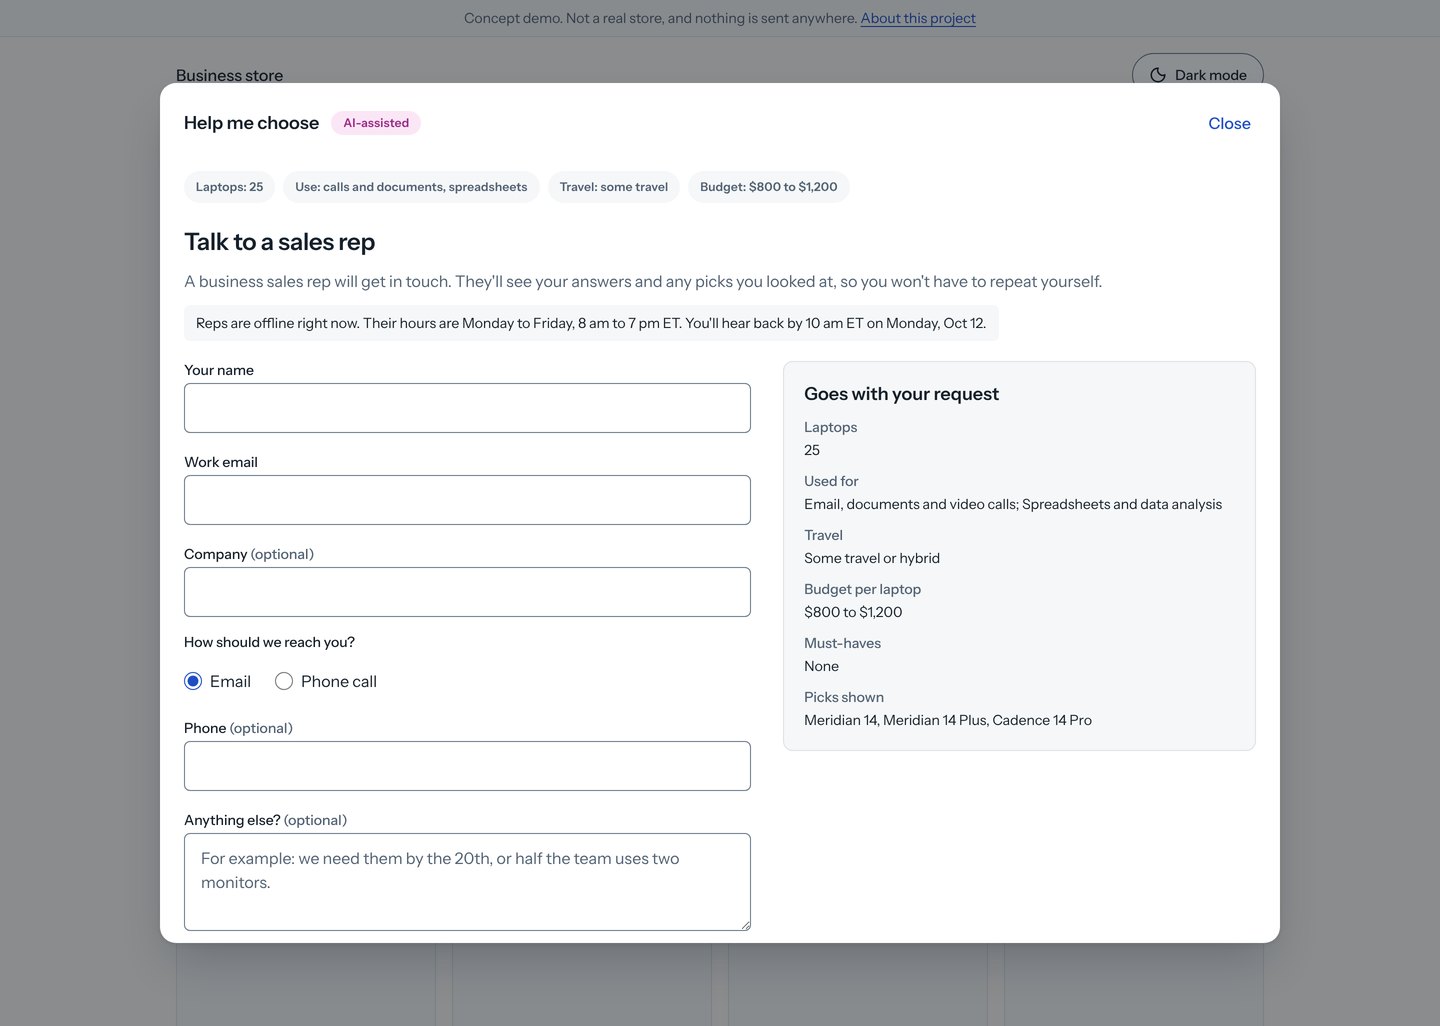
- Human help that closed in the evening. So the concierge works any time, and when it hands off to a sales rep after hours, it promises the next business morning instead of pretending someone is waiting.
From wireframe to final
I sketched four screens in Figma, kept them grayscale so feedback stayed on the flow, then designed and built the final versions directly in code. Each pair shows what changed.
Question step
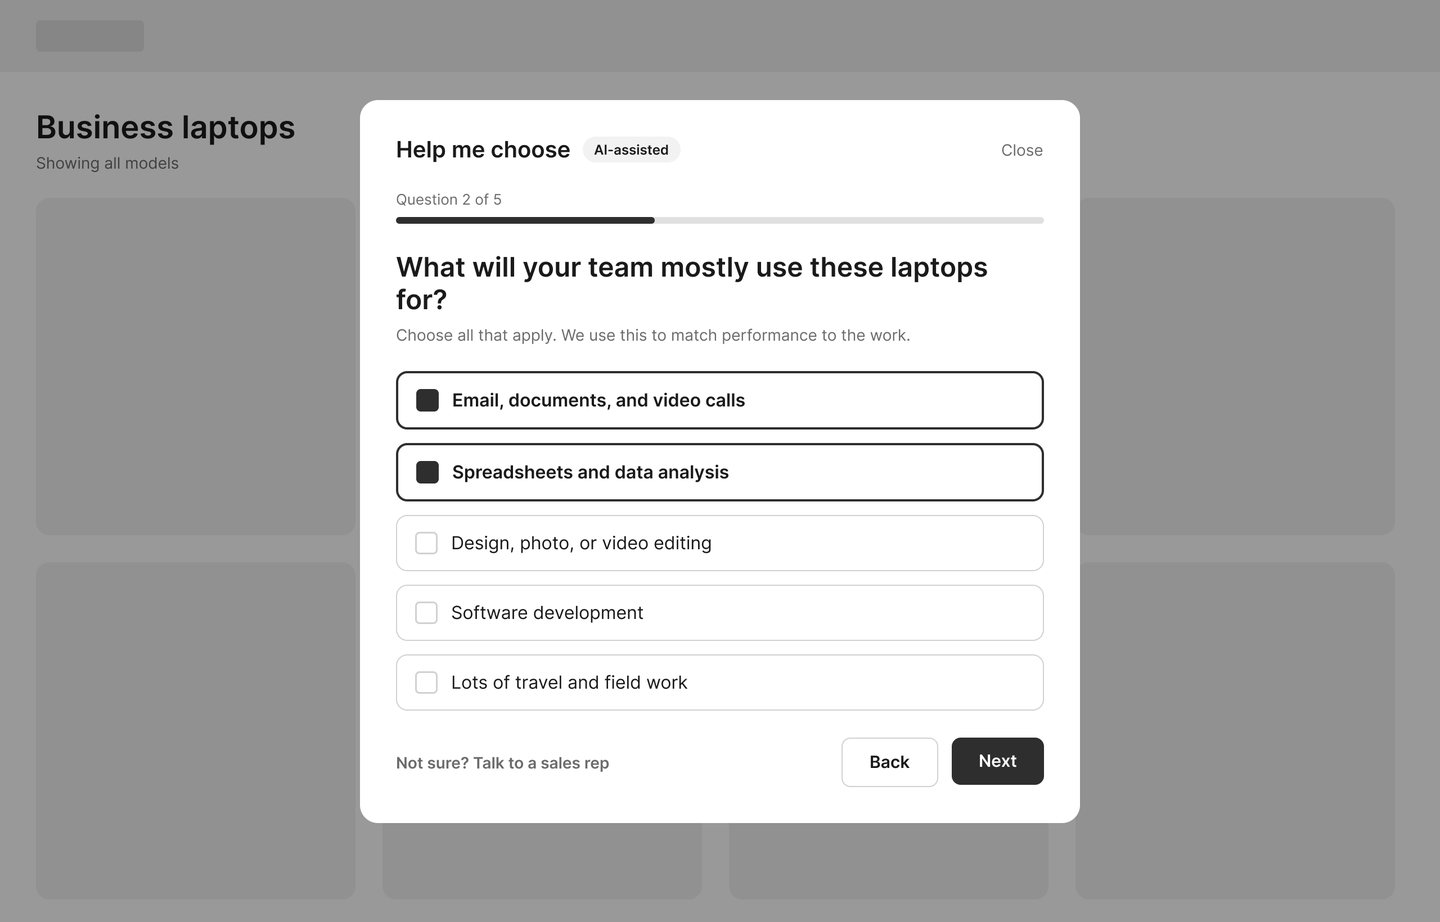
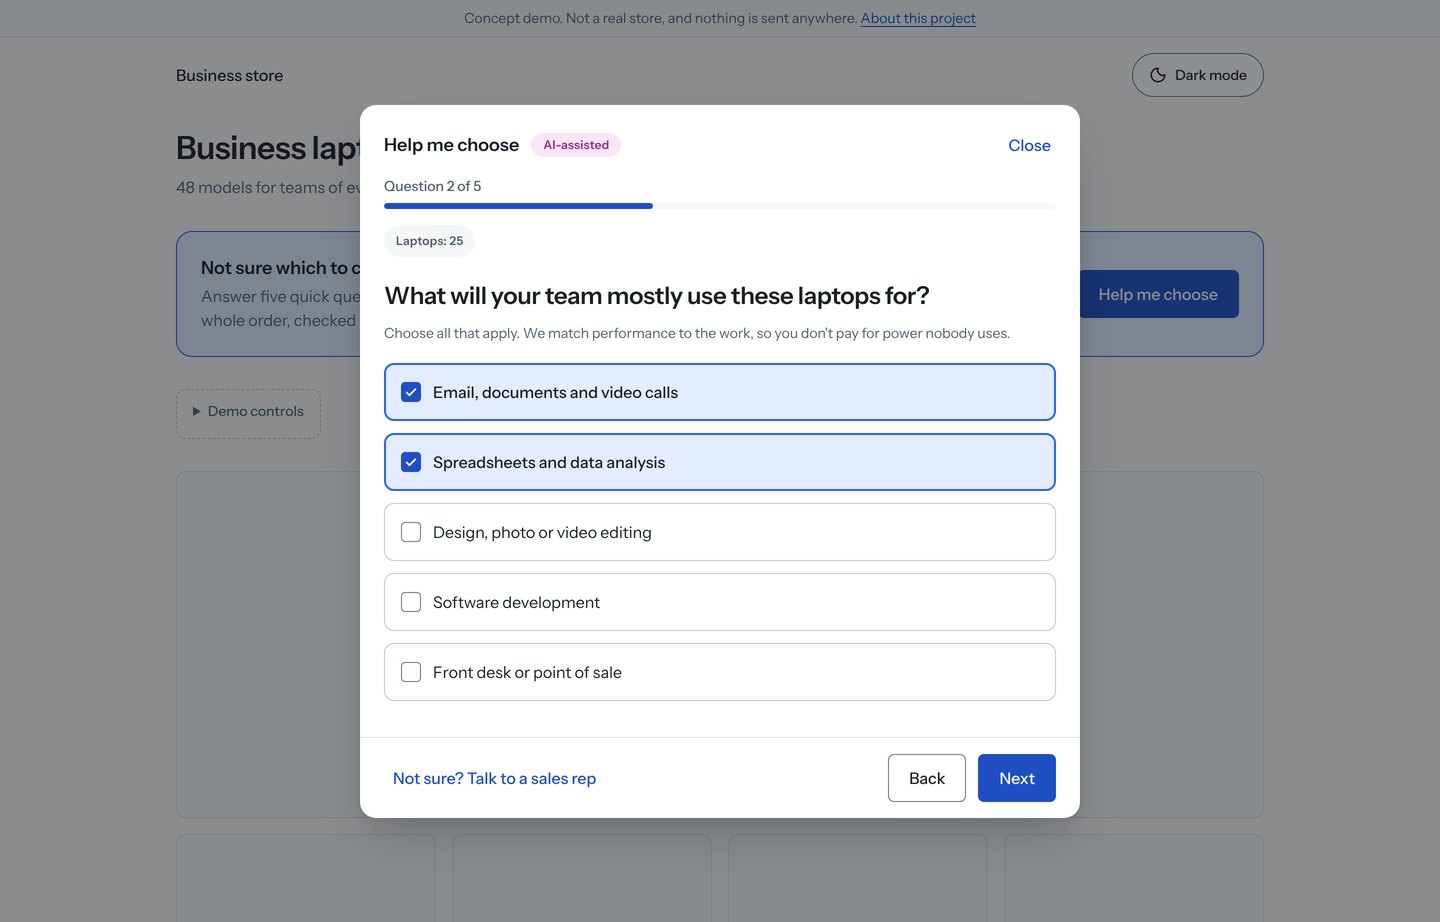
Quantity is now the first question, so every price after it can be shown for the whole order. Earlier answers stay visible as chips you can tap to change, and each question says why it's asked.
Results
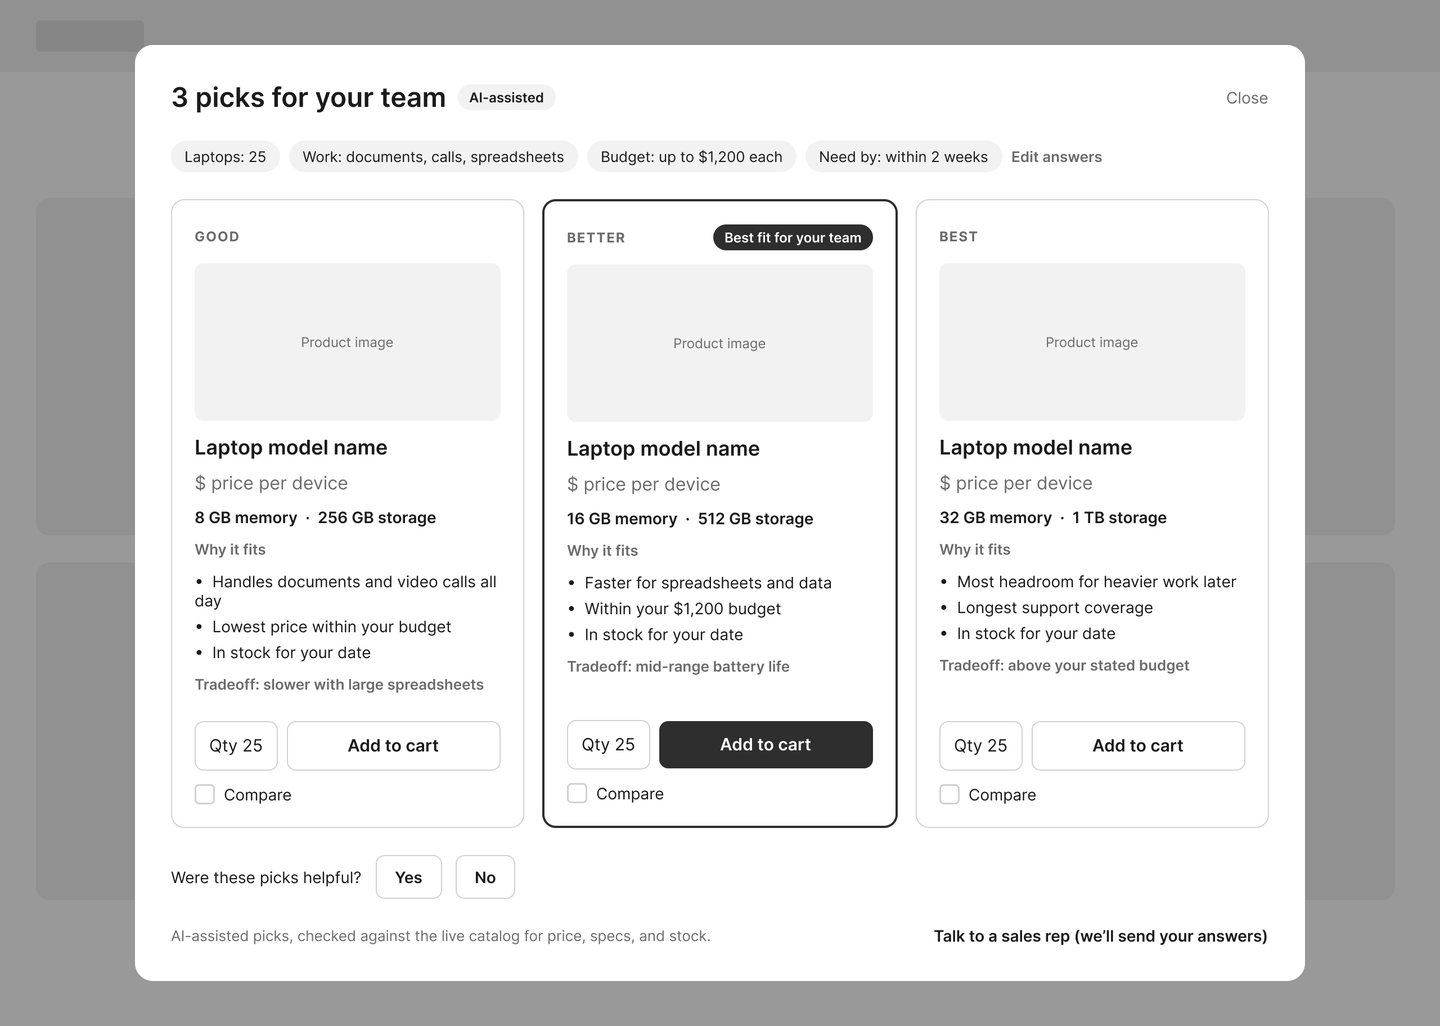
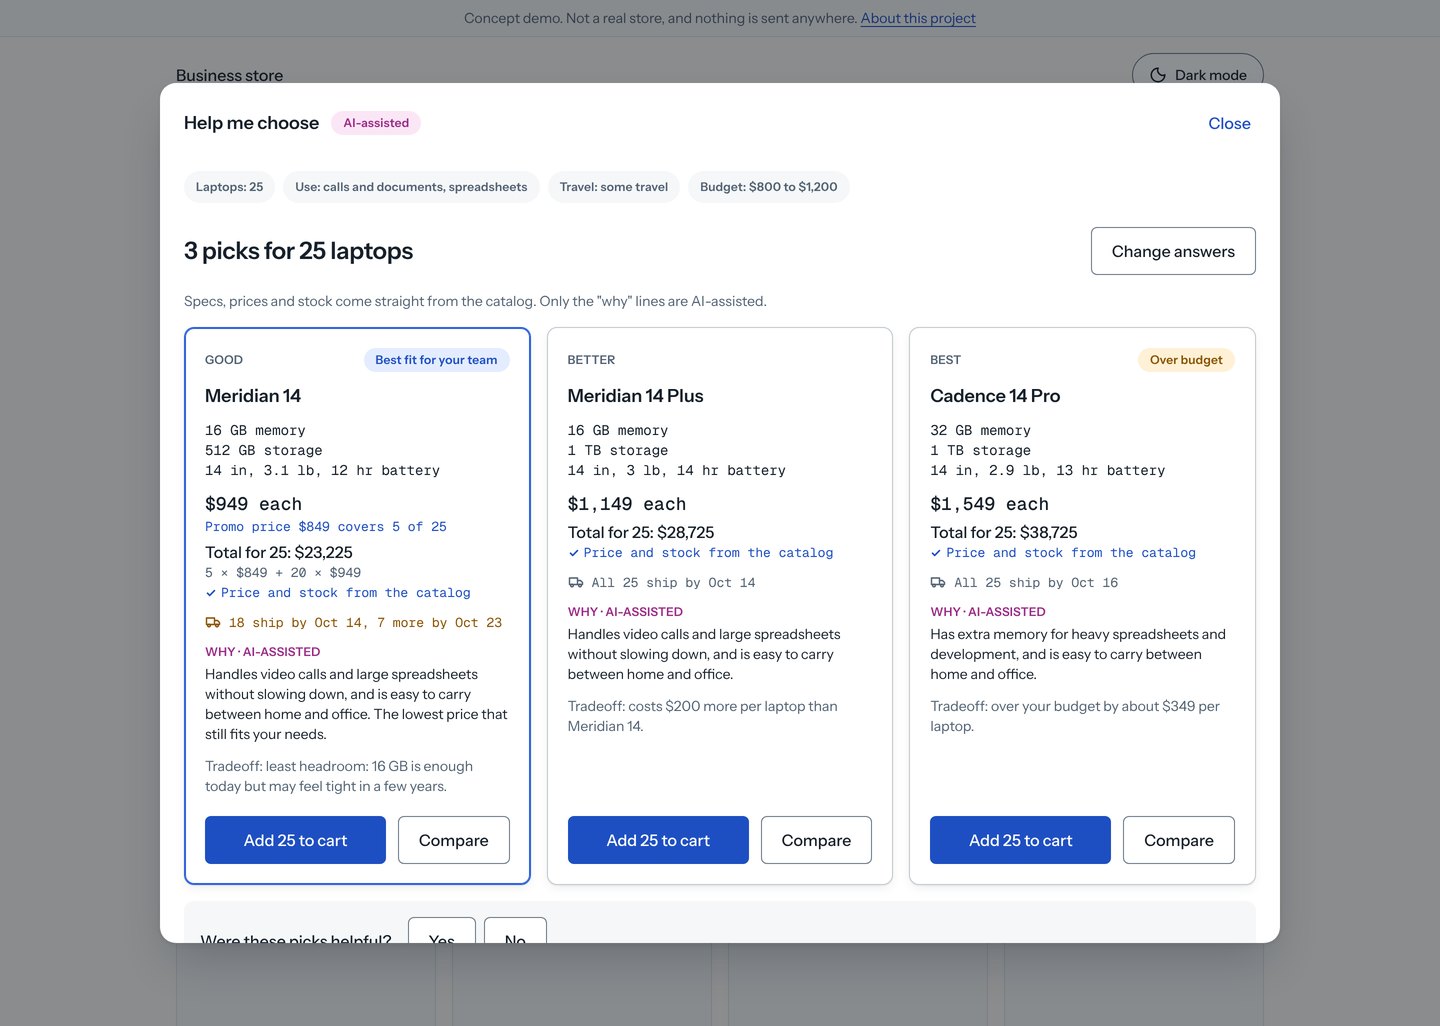
Each pick now shows the team total, the promo math when it applies, and stock dates for the full quantity. Specs and prices are set in mono and marked as coming from the catalog; the reason is labeled AI-assisted. Best fit went to the cheapest pick here, because it matched.
No match in budget
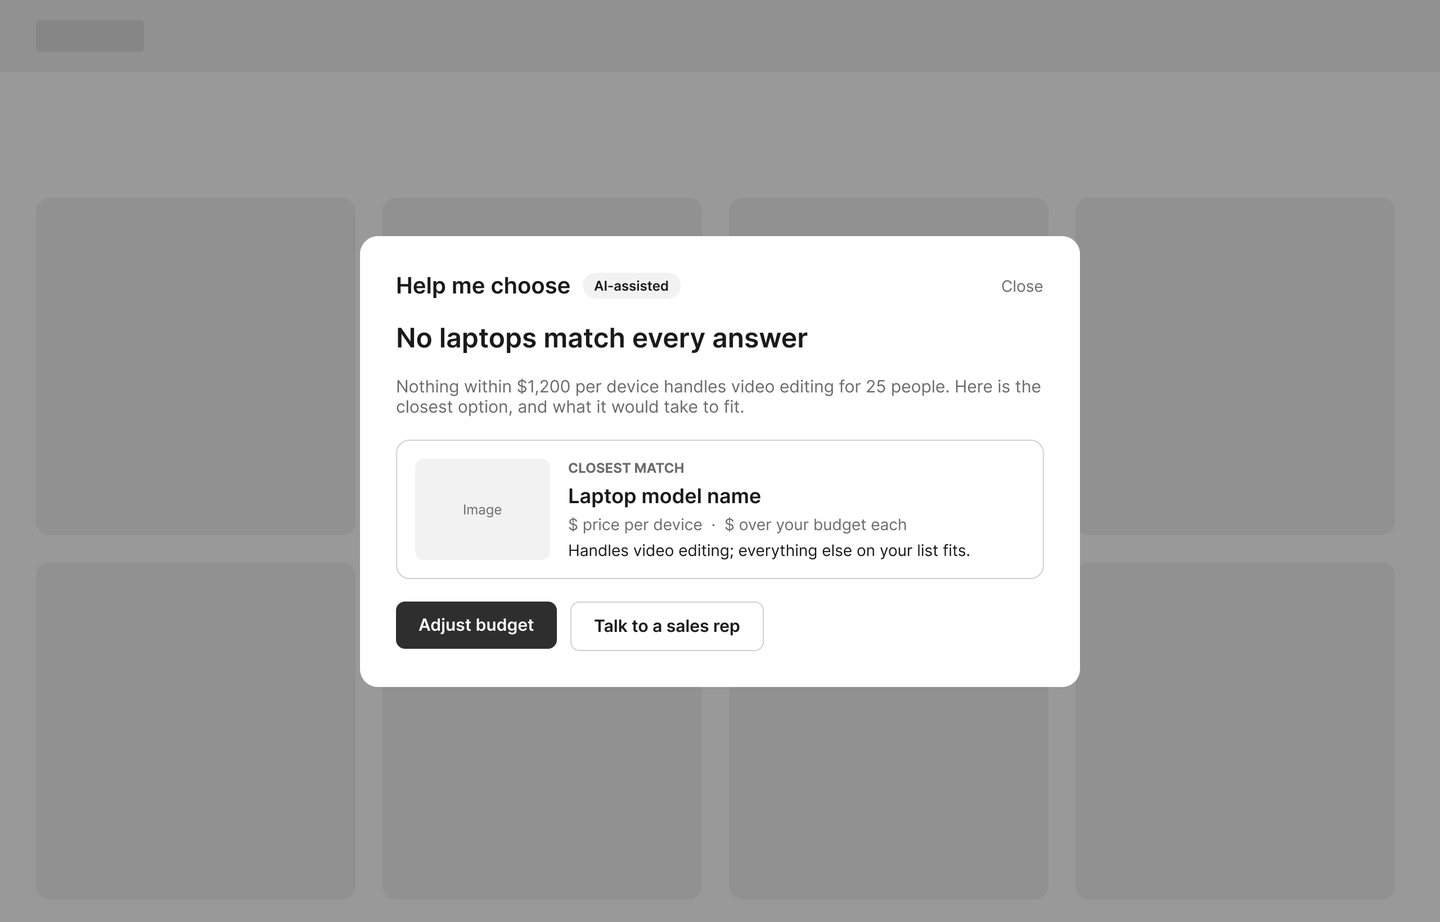
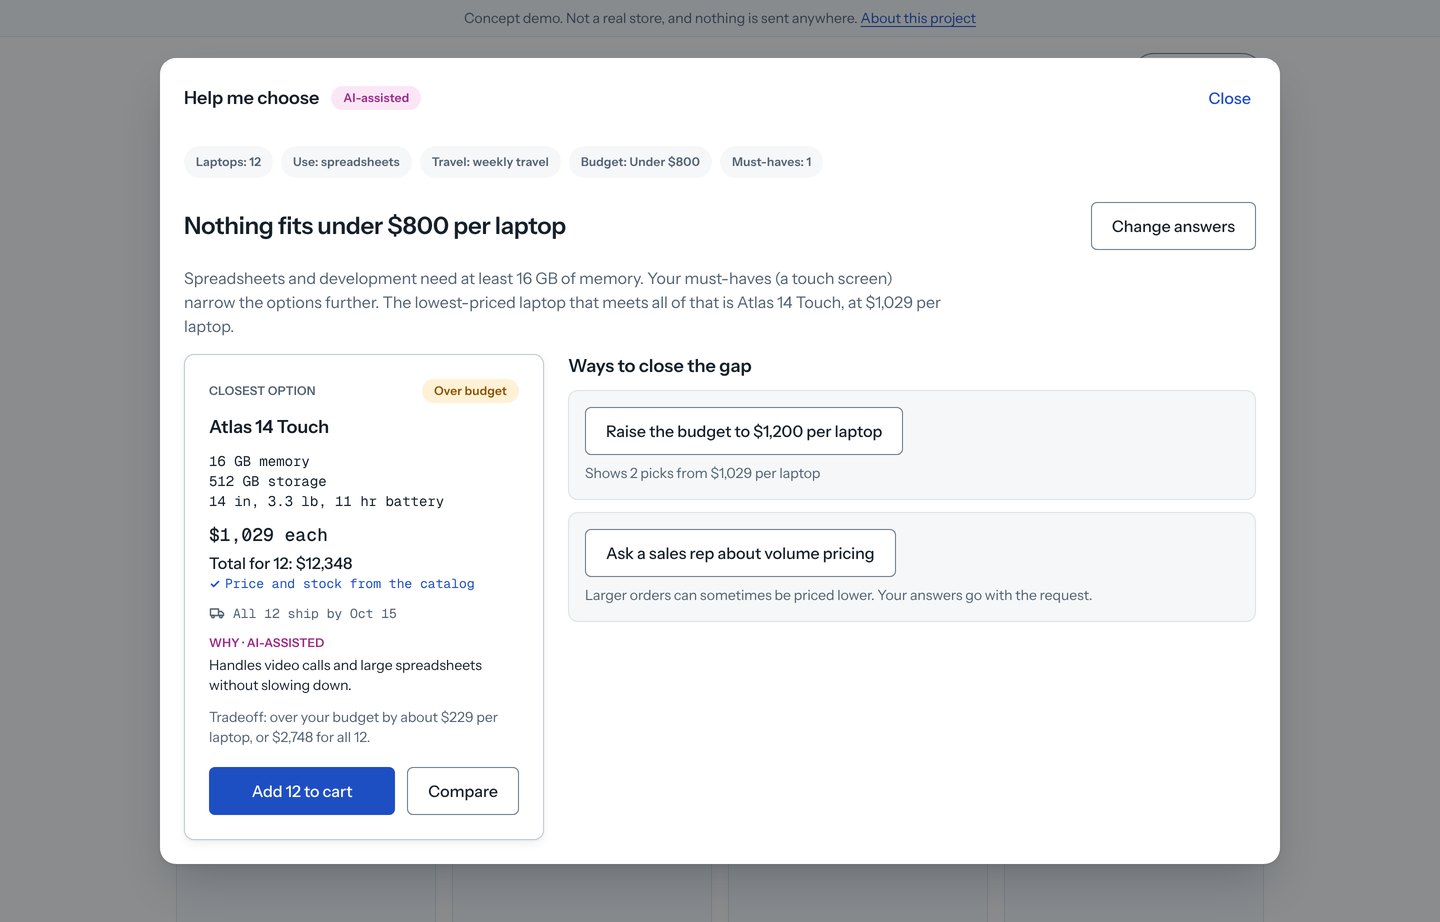
It explains why in plain words, shows the gap per laptop and for the whole order, and offers only fixes it has already tested, each with how many picks it unlocks.
Catalog unavailable
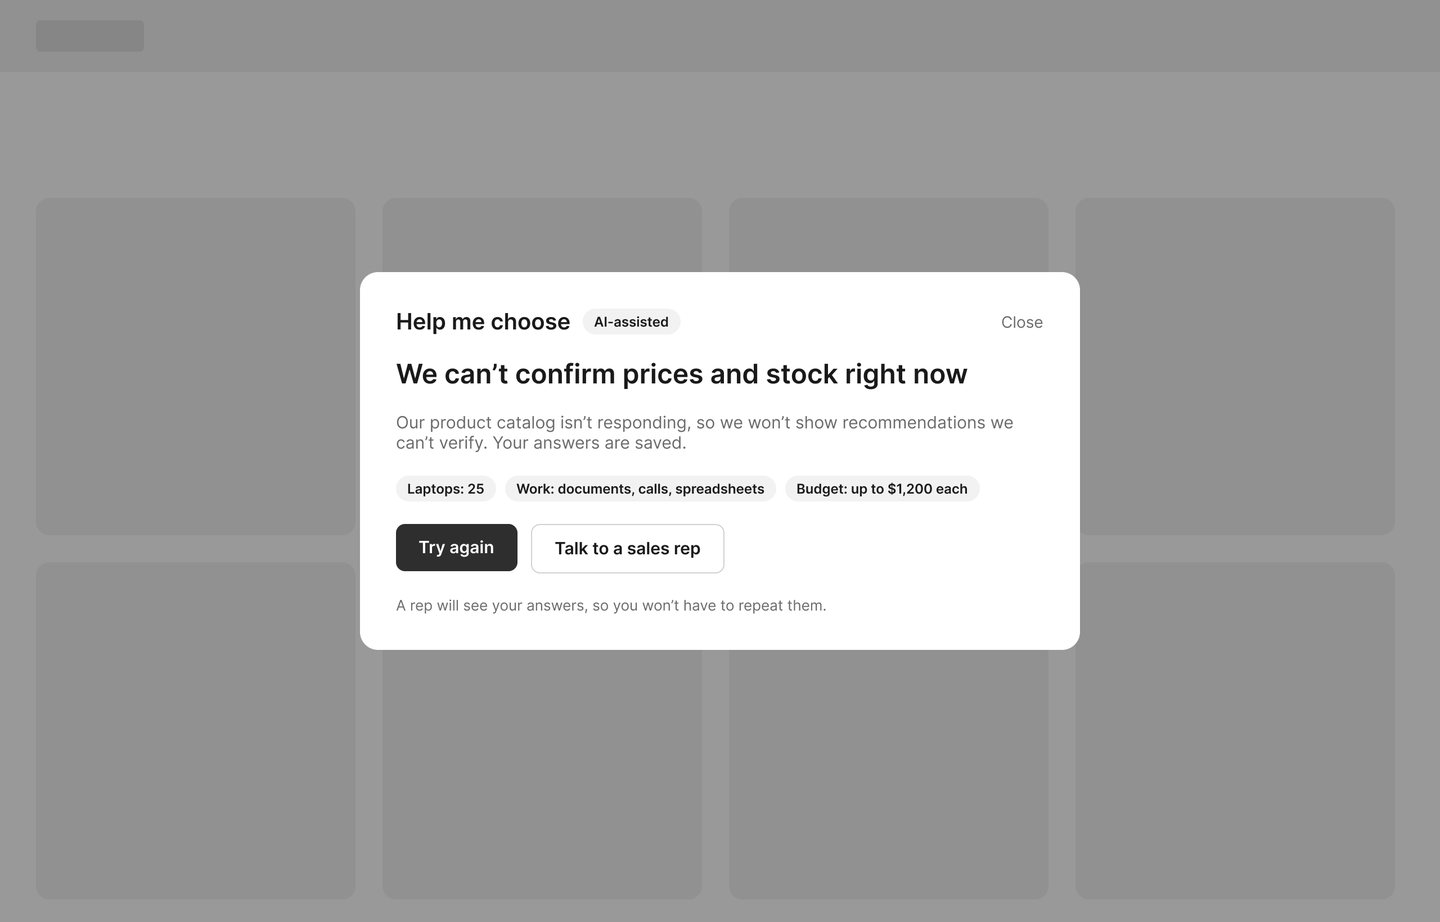
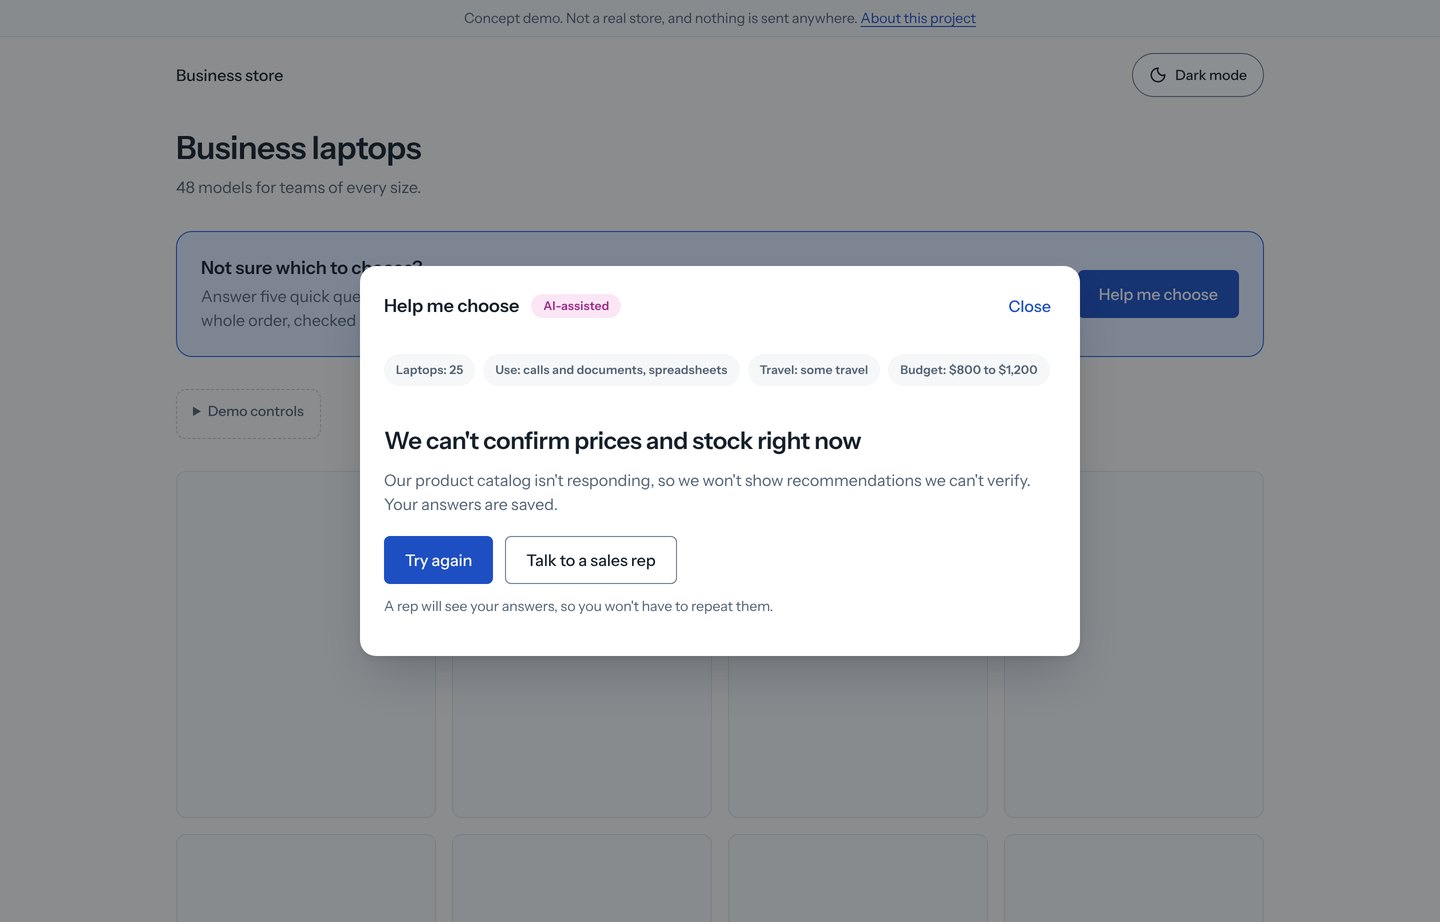
The screen I designed first, and the one that changed least: when the catalog can't be reached, the AI would rather say nothing than guess. Any error in the search lands here too.
Measuring success
The concierge succeeds if more small business visitors buy the right laptops, without more returns or wrong answers. Targets are starting proposals, set against a baseline measured first.
- Primary: conversion rate for sessions that use the concierge, compared with a control group.
- Secondary: time from first question to add-to-cart, and average order value, which shouldn't drop.
- Guardrails: no increase in returns, 100% of specs and prices matching the catalog, and a "Were these picks helpful?" question tracked weekly.
AI quality gets its own plan. Before launch, a test set of about 200 real buyer questions, each with an expert-approved answer, scores whether facts match the catalog, whether the pick fits the stated needs, and whether it behaves safely, like declining to promise discounts. After launch, about 50 real conversations get reviewed each week, plus every "No" on the helpfulness question, and any failure joins the test set so it can't happen twice.
Risks and rollout
The biggest risk is a confident wrong answer, so accuracy gates every step of the rollout.
- Wrong spec, price or stock: every fact is retrieved from the live catalog, and price and stock are shown from the catalog, not generated text.
- Pushy upselling: the best fit is recommended first, and every tier shows its tradeoff.
- Collecting too much data: it only asks about the purchase and stores nothing personal beyond the session without consent.
- Cost per conversation: tracked against revenue lift, with a smaller model for simple questions.
The rollout runs in four steps: pass the 200-question test set offline, a two-week pilot with sales reps flagging bad answers, an A/B test on 10% of traffic, and expansion only if conversion improves and every guardrail holds.
What I built
A working concierge in plain HTML, CSS and JavaScript, with a design system that matches the Figma tokens one to one. Try the live demo.
- Accessible by default: a native dialog that keeps focus inside, real checkboxes and radios, errors that move focus to the field, 44px targets, and WCAG AA contrast in light and dark themes.
- Facts and AI kept apart in the code, not just the design: a catalog file is the only source of specs, prices and stock. Simple rules stand in for the model and only write the "why" and "tradeoff" lines.
- A handoff that respects people's time: the sales rep sees the answers and picks, and the buyer sees honest hours.
If this were real
Next would be connecting a real catalog API, swapping the rules for a model, and running the 200-question test set before any buyer sees it. Then the two-week pilot with sales reps, and the A/B test.